I evaluated 57 LLMs so you don’t have to.
Independent language-model benchmark: 23 tasks, 7 categories, real cost per successful task. No contamination, no partnerships.
claude-fable-5-1-max-effort
automatically
ox-alpha-max
AI for your role
No need to become a prompt expert. Describe your role and need — the iatrust generator returns a structured prompt ready for ChatGPT, Claude or Gemini. Free, no account, in English.
Also: Data analysis · Teaching / Training · Customer support →
Generate my prompt →AI ranking 2026: top 5 LLMs
Full ranking →Models leading the board: coding, reasoning, math — public, reproducible scores updated each release.
Overall score for each model (average of 7 categories) — release 2026-06-25.
AI news
Full blog →
AI Act : l’échéance d’août 2026 qui concerne aussi les entreprises US
Modèles d’IA chinois en 2026 : DeepSeek, Qwen, Kimi, GLM… lequel pour quoi ?
NVIDIA rachète Hugging Face pour près de 13 milliards de dollars
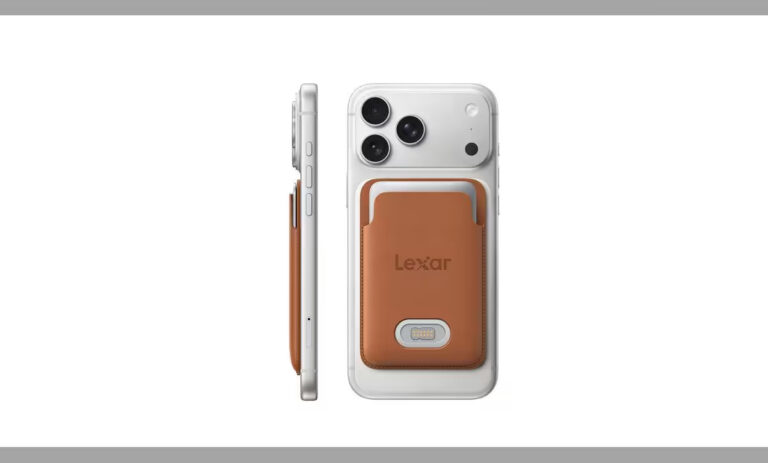
Lexar Muse : un SSD portable de 3,8 mm pensé pour l’iPhone
Qwen3.8-27B en local : un 27B qui tient sur 16 Go avec LM Studio
MiniMax M2.5 : benchmarks de code, tarification et guide
How to find the AI that fits your job
No need to read everything: every model is benchmarked, scored, filterable by metric — then our detailed rankings recommend the AI for your role.
Benchmark
Every listed AI is evaluated on the same 23 fresh, verifiable tasks
Scores
Overall grade + 7 categories: coding, reasoning, math, agents…
Filters
Isolate the metric that matters: performance, cost, open weights, org
Real cost
Dollars per successful task — the true price of your usage, not the sticker rate
Skill report
A dedicated ranking per skill with analysis, podium and FAQ
Recommendation
Our data-driven verdict: which AI to pick for your job
The reference
“A good LLM benchmark must ask fresh questions, uncontaminated by training data — automatic grading, regular updates.”